NLP
Rule-based sentence boundaries for Urdu, where punctuation alone is not enough.
Notebook complete; the demo runs the same rules on any Urdu text you paste.
PythonregexurduhackSentencePieceTypeScript (demo)
Overview
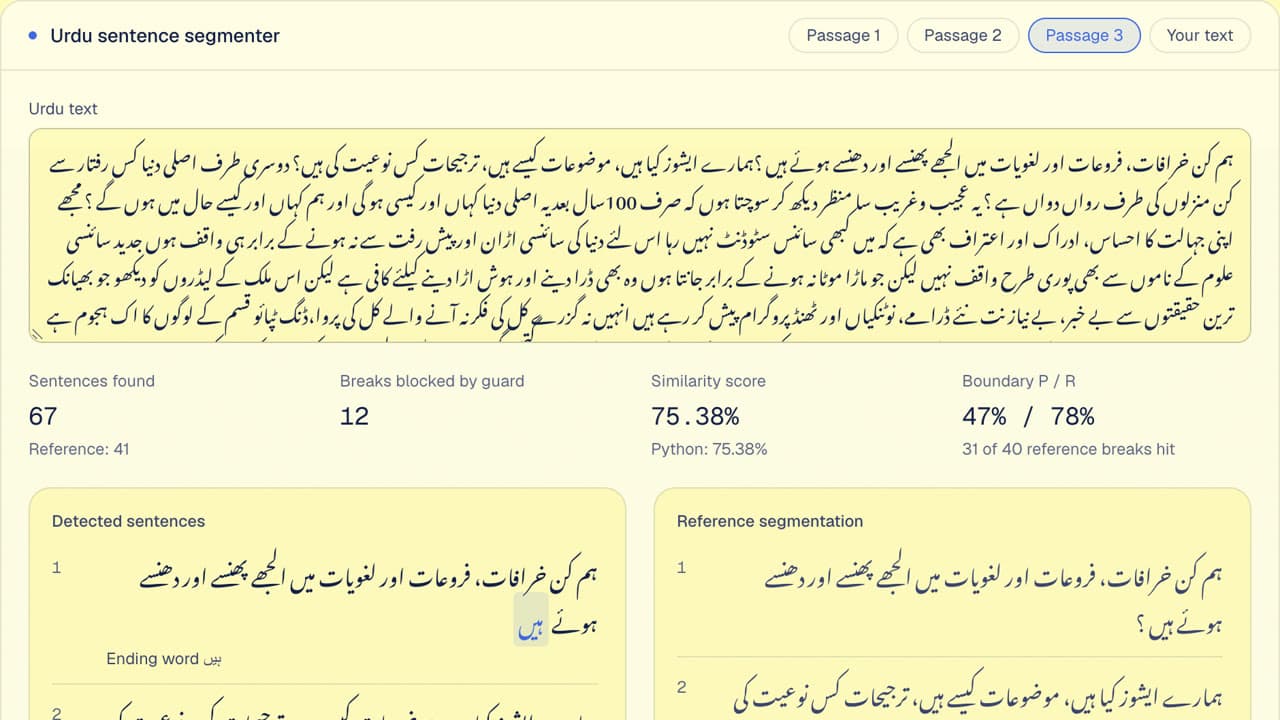
A custom Urdu sentence tokenizer that combines punctuation with lists of sentence-final verbs and auxiliaries and guards on conjunctions, compared with Urduhack, plus SentencePiece subword training on an 11.5 MB Urdu corpus.
Interactive demo
The rule set from the notebook: sentence-final punctuation plus Urdu verb and auxiliary endings, with conjunctions as guards.
Recorded results
- Sentence similarity, passage 3
- 75.38%
- Cosine-similarity proxy, as recorded; not boundary F1
- Source: i21_1697.ipynb, cell 26
- Passages 1 and 2
- 66.37% / 67.96%
- Same metric, reproduced from the notebook code on its other two passages
- Source: Reproduced from i21_1697.ipynb cells 19, 22, 25, 26