What transfer learning buys on CIFAR-10: 69% from scratch, 97% fine-tuned.
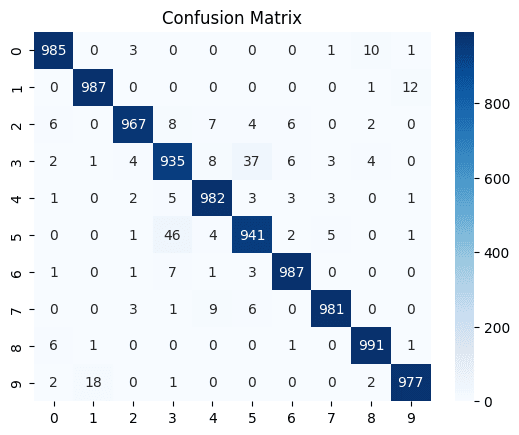
Notebook with recorded results and confusion matrices.
Overview
A controlled comparison on CIFAR-10 between a small convolutional network trained from scratch and a pretrained ViT-Tiny fine-tuned at 224 pixels. A from-scratch ViT (patch 4, depth 6, 8 heads) is also implemented.
Problem
Vision Transformers lack the locality bias of convolutions and are data hungry; the question is how much pretraining changes that on a small dataset.
Approach
Train both models for 10 epochs with matched evaluation: a two-block CNN with BatchNorm and dropout, and timm's vit_tiny_patch16_224 fine-tuned with AdamW at 1e-4 and a step learning-rate schedule.
Architecture
Select a component to see what it does. Blue packets show the direction data moves.
- CIFAR-10 image to SimpleCNN
- CIFAR-10 image to Resize 224
- Resize 224 to ViT-Tiny
- SimpleCNN to Evaluation
- ViT-Tiny to Evaluation
Recorded results
- SimpleCNN validation accuracy
- 69.28%
- 10 epochs, from scratch
- Source: Vit_Vs_CNN(CIFAR_10).ipynb, cell 12
- ViT-Tiny validation accuracy
- 97.33%
- 10 epochs, ImageNet-pretrained, fine-tuned
- Source: Vit_Vs_CNN(CIFAR_10).ipynb, cell 13
Limitations
- The validation split is the CIFAR-10 test set, so there is no separate held-out test.
- The from-scratch ViT is implemented but its training run is not recorded.